fileinputformat不同mapreduce程序可以连续运行吗?比如说多个这样的程序,用上一个的输出作为下一个的输入,求
fileinputformat 时间:2021-06-08 阅读:()
mapreduce中reducenum数量对程序有什么影响
mapreduce中的reduce数量是由什么来进行控制的呢? 1、numReduceTasks 如下是用来进行测试的一段wordcount的代码 import java.io.IOException; import java.util.StringTokenizer; .apache.hadoop.fs.Path; .apache.hadoop.io.IntWritable; .apache.hadoop.io.LongWritable; .apache.hadoop.io.Text; .apache.hadoop.mapred.JobConf; .apache.hadoop.mapreduce.Job; .apache.hadoop.mapreduce.Mapper; .apache.hadoop.mapreduce.Partitioner; .apache.hadoop.mapreduce.Reducer; .apache.hadoop.mapreduce.lib.input.FileInputFormat; .apache.hadoop.mapreduce.lib.output.FileOutputFormat; public class PartTest { public static void main(String[] args){ Path inFile = new Path(args[0]); Path outFile = new Path(args[1]); Job job; try { job = Job.getInstance(); job.setJarByClass(PartTest.class); FileInputFormat.addInputPath(job , inFile); FileOutputFormat.setOutputPath(job, outFile); job.setReducerClass(PartTestreducer.class); job.setMapperClass(PartTestmapper.class); job.setMapOutputKeyClass(Text.class); job.setMapOutputValueClass(IntWritable.class); job.setOutputKeyClass(Text.class); job.setOutputValueClass(IntWritable.class); try { job.waitForCompletion(true); } catch (ClassNotFoundException e) { // TODO Auto-generated catch block e.printStackTrace(); } catch (InterruptedException e) { // TODO Auto-generated catch block e.printStackTrace(); } } catch (IOException e) { // TODO Auto-generated catch block e.printStackTrace(); } /** * InputFormat描述map-reduce中对job的输入定义 * setInputPaths():为map-reduce job设置路径数组作为输入列表 * setInputPath():为map-reduce job设置路径数组作为输出列表 */ } } class PartTestmapper extends Mapper然后使用 hadoop fs -ls /tmp/part/out2 可以看到/tmp/part/out2文件夹中生成了3个part文件: 所以可以使用 setNumReduceTasks 来设置reduce的数量 2、mapreduce的分区 我们在原来的代码的最后一段加上如下代码: class PartTestPartitioner extends Partitioner
class,第二个参数为map任务的alue。
class,第三个参数为分区的数量,默认为1 public int getPartition(Text key, IntWritable value, int numPartitions) { // TODO Auto-generated method stub if(key.toString().startsWith("h")){ return 0%numPartitions; } else if(key.toString().startsWith("s")){ return 1%numPartitions; } else{ return 2%numPartitions; } } } 这段代码的含义是: 将以h开头的统计结果输出到part-r-00000 将以s开头的统计结果输出到part-r-00001 将以其他字母开头的统计结果输出到part-r-00002 对原有代码进行如下修改: job = Job.getInstance(); job.setJarByClass(PartTest.class); FileInputFormat.addInputPath(job , inFile); FileOutputFormat.setOutputPath(job, outFile); job.setNumReduceTasks(3); job.setPartitionerClass(PartTestPartitioner.class); job.setReducerClass(PartTestreducer.class); job.setMapperClass(PartTestmapper.class); job.setMapOutputKeyClass(Text.class); job.setMapOutputValueClass(IntWritable.class); job.setOutputKeyClass(Text.class); job.setOutputValueClass(IntWritable.class); 新加了一行代码:job.setPartitionerClass(PartTestPartitioner.class); 将代码重新打包上传,执行: hadoop jar parttest.jar "PartTest" "/tmp/test.txt" "/tmp/part/out3" 将结果输出到/tmp/part/out3目录 可以看到启动了3个reduce任务。
然后使用 hadoop fs -ls /tmp/part/out3 可以看到/tmp/part/out3文件夹中生成了3个part文件: 分别查看三个文件: 可以看到输出结果已经分别输出到对应的分区文件。
注意: job.setNumReduceTasks(3); job.setPartitionerClass(PartTestPartitioner.class); NumReduceTasks的数量不能小于partitioner的数量,否则结果会写到part-r-00000中 分类: HADOOP
mapreduce 怎么查看每个reducer处理的数据量
您好,第一种方法是用Mapper读取文本文件用StringTokenizer对读取文件内的每一行的数字(Hadoop处理文本文件时,处理时是一行一行记取的)进行分隔,获取每一个数字,然后求和,再将求得的值按Key/Value格式写入Context,最后用Reducer对求得中间值进行汇总求和,得出整个文件所有数字的和。第二种方法是用Mapper读取文本文件用StringTokenizer对文件内的数字进行分隔,获取每一个数字,并救出文件中该数字有多少个,在合并过程中,求出每个数字在文件中的和,最后用Reducer对求得每个数字求得的和进行汇总求和,得出整个文件所有数字的和。
.hadoop; import java.io.IOException; import java.util.StringTokenizer; .apache.hadoop.conf.Configuration; .apache.hadoop.fs.Path; .apache.hadoop.io.LongWritable; .apache.hadoop.io.Text; .apache.hadoop.mapreduce.Job; .apache.hadoop.mapreduce.Mapper; .apache.hadoop.mapreduce.Reducer; .apache.hadoop.mapreduce.lib.input.FileInputFormat; .apache.hadoop.mapreduce.lib.output.FileOutputFormat; .apache.hadoop.util.GenericOptionsParser; public class NumberSum { //对每一行数据进行分隔,并求和 public static class SumMapper extends Mapper<Object, Text, Text, LongWritable> { private Text word = new Text("sum"); private static LongWritable numValue = new LongWritable(1); public void map(Object key, Text value, Context context) throws IOException, InterruptedException { StringTokenizer itr = new StringTokenizer(value.toString()); long sum = 0; while (itr.hasMoreTokens()) { String s = itr.nextToken(); long val = Long.parseLong(s); sum += val; } numValue.set(sum); context.write(word, numValue); } } // 汇总求和,输出 public static class SumReducer extends Reducer<Text, LongWritable, Text, LongWritable> { private LongWritable result = new LongWritable(); private Text k = new Text("sum"); public void reduce(Text key, Iterable<LongWritable> values, Context context) throws IOException, InterruptedException { long sum = 0; for (LongWritable val : values) { long v = val.get(); sum += v; } result.set(sum); context.write(k, result); } } /** * @param args * @throws Exception */ public static void main(String[] args) throws Exception { Configuration conf = new Configuration(); String[] otherArgs = new GenericOptionsParser(conf, args) .getRemainingArgs(); if (otherArgs.length != 2) { System.err.println("Usage: numbersum <in> <out>"); System.exit(2); } Job job = new Job(conf, "number sum"); job.setJarByClass(NumberSum.class); job.setMapperClass(SumMapper.class); job.setReducerClass(SumReducer.class); job.setOutputKeyClass(Text.class); job.setOutputValueClass(LongWritable.class); FileInputFormat.addInputPath(job, new Path(otherArgs[0])); FileOutputFormat.setOutputPath(job, new Path(otherArgs[1])); System.exit(job.waitForCompletion(true) ? 0 : 1); System.out.println("ok"); } } 第一种实现的方法相对简单,第二种实现方法用到了Combiner类,Hadoop 在 对中间求的的数值进行Combiner时,是通过递归的方式不停地对 Combiner方法进行调用,进而合并数据的。
从两种方法中,我们可以看出Map/Reduce的核心是在怎样对输入的数据按照何种方式是进行Key/Value分对的,分的合理对整个结果输出及算法实现有很大的影响。
spark 读取多个文件支持通配符吗?为什么用通配符提示找不到文件
val wc = sc.textFile("/user/boco/yy/_*").flatMap(_.split()).map((_,1)).groupByKey 直接用*代替,不用加“/”,刚我试过了。而且就算加,怎么会加到*后面啊,加到后面就是找"_*"文件夹了
Hadoop中mapred包和mapreduce包的区别
今天写了段代码突然发现,很多类在mapred和mapreduce中分别都有定义,下面是小菜写的一段代码: public class MyJob extends Configured implements Tool { public static class MapClass extends MapReduceBase implements Mapper<Text, Text, Text, Text> {// public void map(Text key, Text value, OutputCollector<Text, Text> output, Reporter reporter) throws IOException { output.collect(value, key); } } public static class Reduce extends MapReduceBase implements Reducer<Text, Text, Text, Text> { @Override public void reduce(Text key, Iterator<Text> values, OutputCollector<Text, Text> output, Reporter reporter) throws IOException { String csv = ""; while (values.hasNext()) { csv += csv.length() > 0 ? "," : ""; csv += values.next().toString(); } output.collect(key, new Text(csv)); } } @Override public int run(String[] args) throws Exception { Configuration conf = getConf(); JobConf job = new JobConf(conf, MyJob.class); //JobConf job = new JobConf(conf, MyJob.class); Path in = new Path(args[0]); Path out = new Path(args[1]); FileInputFormat.setInputPaths(job, in); FileOutputFormat.setOutputPath(job, out); job.setJobName("MyJob"); job.setMapperClass(MapClass.class); job.setReducerClass(Reduce.class); job.setInputFormat(KeyValueTextInputFormat.class); job.setOutputFormat(TextOutputFormat.class); job.setOutputKeyClass(Text.class); job.setOutputValueClass(Text.class); job.set("key.value.separator.in.input.line", ","); JobClient.runJob(job); return 0; } public static void main(String[] args) throws Exception { // TODO Auto-generated method stub int res = ToolRunner.run(new Configuration(), new MyJob(), args); System.exit(res); } } 主要看run方法: 上面代码中的Jobconf无可厚非,只有在mapred包中有定义,这个没问题。但是FileInputFormat和FileOutputFormat在mapred和mapreduce中都有定义,刚开始脑海里对这些都没有概念,就引用了mapreduce中的FileInputFormat和FIleOutputFormat。
这样操作就带来了后面的问题 FileInputFormat.setInputPaths(job, in); FileOutputFormat.setOutputPath(job, out); 这两条语句不能通过编译,为什么呢,因为FileInputFormat.setInputPaths和FileOutputFormat.setOutputPath的第一个参数都是Job,而不是JobConf,找了很多资料,由于对Hadoop了解少,所以找资料没有方向感,这也是学习新东西效率低下的原因,如果有哪位大牛,知道怎么克服效率低下的问题,请不吝赐教! 后来,无意中,看到mapred包中也有这两个类的定义,于是火箭速度修改为mapred下的包,OK,顺利通过编译! 下面还有 job.setOutputFormat(TextOutputFormat.class);语句编译不同通过,提示参数需要扩展。
。
。
的参数;于是小菜也去mapred下面查找是否存在此类,正如期望,也存在此类,当即立段,修改为此包下的类,顺利编译通过,此时,颇有成就感! 可是现在小菜发现,mapred包下和mapreduce包下同时都存在又相应的类,不知道是为什么,那么下面就有目标的请教搜索引擎啦,呵呵,比刚才有很大进步。
结果令小菜很失望,就找到了一个符合理想的帖子。
但是通过这个帖子,小菜知道了,mapred代表的是hadoop旧API,而mapreduce代表的是hadoop新的API。
OK,小菜在google输入框中输入“hadoop新旧API的区别”,结果很多。
看了之后,又结合权威指南归结如下: 1. 首先第一条,也是小菜今天碰到这些问题的原因,新旧API不兼容。
所以,以前用旧API写的hadoop程序,如果旧API不可用之后需要重写,也就是上面我的程序需要重写,如果旧API不能用的话,如果真不能用,这个有点儿小遗憾! 2. 新的API倾向于使用抽象类,而不是接口,使用抽象类更容易扩展。
例如,我们可以向一个抽象类中添加一个方法(用默认的实现)而不用修改类之前的实现方法。
因此,在新的API中,Mapper和Reducer是抽象类。
3. 新的API广泛使用context object(上下文对象),并允许用户代码与MapReduce系统进行通信。
例如,在新的API中,MapContext基本上充当着JobConf的OutputCollector和Reporter的角色。
4. 新的API同时支持"推"和"拉"式的迭代。
在这两个新老API中,键/值记录对被推mapper中,但除此之外,新的API允许把记录从map()方法中拉出,这也适用于reducer。
分批处理记录是应用"拉"式的一个例子。
5. 新的API统一了配置。
旧的API有一个特殊的JobConf对象用于作业配置,这是一个对于Hadoop通常的Configuration对象的扩展。
在新的API中,这种区别没有了,所以作业配置通过Configuration来完成。
作业控制的执行由Job类来负责,而不是JobClient,并且JobConf和JobClient在新的API中已经荡然无存。
这就是上面提到的,为什么只有在mapred中才有Jobconf的原因。
6. 输出文件的命名也略有不同,map的输出命名为part-m-nnnnn,而reduce的输出命名为part-r-nnnnn,这里nnnnn指的是从0开始的部分编号。
这样了解了二者的区别就可以通过程序的引用包来判别新旧API编写的程序了。
小菜建议最好用新的API编写hadoop程序,以防旧的API被抛弃!!!
fileinputformat是抽象类吗
不是抽象类,你看看API啊,继承于InputStream是抽象类, FileInputStream不是,它有3个构造器 FileInputStream(File file) Creates a FileInputStream by opening a connection to an actual file, the file named by the File object file in the file system. FileInputStream(FileDescriptor fdObj) Creates a FileInputStream by using the file descriptor fdObj, which represents an existing connection to an actual file in the file system. FileInputStream(String name) Creates a FileInputStream by opening a connection to an actual file, the file named by the path name name in the file system.不同mapreduce程序可以连续运行吗?比如说多个这样的程序,用上一个的输出作为下一个的输入,求
可以的。最简单的方式就是在一个类里定义 map1 reduce1 map2 reduce2 map3 reduce3 map2 的输入设为map1的输出 map3 的输入可以设为map2和map3的输入。
- fileinputformat不同mapreduce程序可以连续运行吗?比如说多个这样的程序,用上一个的输出作为下一个的输入,求相关文档
- fileinputformatHadoop,Combiner有什么用?
- fileinputformatmapreduce 键值对怎么定义的
- fileinputformathadoop 怎么设置多个输入路径
RAKsmart:美国圣何塞服务器限量秒杀$30/月起;美国/韩国/日本站群服务器每月189美元起
RAKsmart怎么样?RAKsmart是一家由华人运营的国外主机商,提供的产品包括独立服务器租用和VPS等,可选数据中心包括美国加州圣何塞、洛杉矶、中国香港、韩国、日本、荷兰等国家和地区数据中心(部分自营),支持使用PayPal、支付宝等付款方式,网站可选中文网页,提供中文客服支持。本月商家继续提供每日限量秒杀服务器月付30.62美元起,除了常规服务器外,商家美国/韩国/日本站群服务器、1-10...
亚洲云Asiayu,成都云服务器 4核4G 30M 120元一月
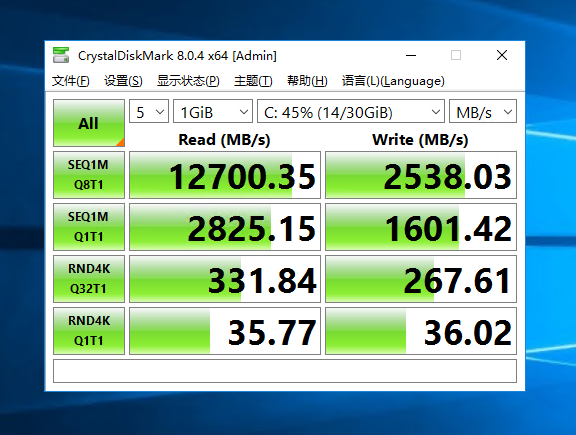
点击进入亚云官方网站(www.asiayun.com)公司名:上海玥悠悠云计算有限公司成都铂金宿主机IO测试图亚洲云Asiayun怎么样?亚洲云Asiayun好不好?亚云由亚云团队运营,拥有ICP/ISP/IDC/CDN等资质,亚云团队成立于2018年,经过多次品牌升级。主要销售主VPS服务器,提供云服务器和物理服务器,机房有成都、美国CERA、中国香港安畅和电信,香港提供CN2 GIA线路,CE...
Friendhosting,美国迈阿密机房新上线,全场45折特价优惠,100Mbps带宽不限流量,美国/荷兰/波兰/乌兰克/瑞士等可选,7.18欧元/半年
近日Friendhosting发布了最新的消息,新上线了美国迈阿密的云产品,之前的夏季优惠活动还在进行中,全场一次性45折优惠,最高可购买半年,超过半年优惠力度就不高了,Friendhosting商家的优势就是100Mbps带宽不限流量,有需要的朋友可以尝试一下。Friendhosting怎么样?Friendhosting服务器好不好?Friendhosting服务器值不值得购买?Friendho...
fileinputformat为你推荐
-
winhttp什么是winhttp.dii水晶易表如何在win7环境和office2010环境下成功安装水晶易表y码S`M`XXL`L`XL身高体重分别是多少?腾讯公告官网公告是什么搜索引擎的概念搜索引擎营销的概念是什么?小四号字word里的小四号字在Photoshop里是指多少点字体?awv请问awv是什么样的格式啊?模式识别算法模式识别的简史审计平台什么叫数据库审计系统?微信智能机器人微信群机器人是怎么实现的