fileinputformatHadoop,Combiner有什么用?
fileinputformat 时间:2021-06-08 阅读:()
如何使用Hadoop的Partitioner
Hadoop里面的MapReduce编程模型,非常灵活,大部分环节我们都可以重写它的API,来灵活定制我们自己的一些特殊需求。今天散仙要说的这个分区函数Partitioner,也是一样如此,下面我们先来看下Partitioner的作用: 对map端输出的数据key作一个散列,使数据能够均匀分布在各个reduce上进行后续操作,避免产生热点区。
Hadoop默认使用的分区函数是Hash Partitioner,源码如下: /** Partition keys by their {@link Object#hashCode()}. */ public class HashPartitioner<K, V> extends Partitioner<K, V> { /** Use {@link Object#hashCode()} to partition. */ public int getPartition(K key, V value, int numReduceTasks) { //默认使用key的hash值与上int的最大值,避免出现数据溢出 的情况 return (key.hashCode() & Integer.MAX_VALUE) % numReduceTasks; } } 大部分情况下,我们都会使用默认的分区函数,但有时我们又有一些,特殊的需求,而需要定制Partition来完成我们的业务,案例如下: 对如下数据,按字符串的长度分区,长度为1的放在一个,2的一个,3的各一个。
河南省;1 河南;2 中国;3 中国人;4 大;1 小;3 中;11 这时候,我们使用默认的分区函数,就不行了,所以需要我们定制自己的Partition,首先分析下,我们需要3个分区输出,所以在设置reduce的个数时,一定要设置为3,其次在partition里,进行分区时,要根据长度具体分区,而不是根据字符串的hash码来分区。
核心代码如下: /** * Partitioner * * * */ public static class PPartition extends Partitioner<Text, Text>{ @Override public int getPartition(Text arg0, Text arg1, int arg2) { /** * 自定义分区,实现长度不同的字符串,分到不同的reduce里面 * * 现在只有3个长度的字符串,所以可以把reduce的个数设置为3 * 有几个分区,就设置为几 * */ String key=arg0.toString(); if(key.length()==1){ return 1%arg2; }else if(key.length()==2){ return 2%arg2; }else if(key.length()==3){ return 3%arg2; } return 0; } } 全部代码如下: .partition.test; import java.io.IOException; .apache.hadoop.fs.FileSystem; .apache.hadoop.fs.Path; .apache.hadoop.io.LongWritable; .apache.hadoop.io.Text; .apache.hadoop.mapred.JobConf; .apache.hadoop.mapreduce.Job; .apache.hadoop.mapreduce.Mapper; .apache.hadoop.mapreduce.Partitioner; .apache.hadoop.mapreduce.Reducer; .apache.hadoop.mapreduce.lib.db.DBConfiguration; .apache.hadoop.mapreduce.lib.db.DBInputFormat; .apache.hadoop.mapreduce.lib.input.FileInputFormat; .apache.hadoop.mapreduce.lib.output.FileOutputFormat; .apache.hadoop.mapreduce.lib.output.MultipleOutputs; .apache.hadoop.mapreduce.lib.output.TextOutputFormat; .qin.operadb.PersonRecoder; .qin.operadb.ReadMapDB; /** * @author qindongliang * * 大数据交流群:376932160 * * * **/ public class MyTestPartition { /** * map任务 * * */ public static class PMapper extends Mapper<LongWritable, Text, Text, Text>{ @Override protected void map(LongWritable key, Text value,Context context) throws IOException, InterruptedException { // System.out.println("进map了"); //mos.write(namedOutput, key, value); String ss[]=value.toString().split(";"); context.write(new Text(ss[0]), new Text(ss[1])); } } /** * Partitioner * * * */ public static class PPartition extends Partitioner<Text, Text>{ @Override public int getPartition(Text arg0, Text arg1, int arg2) { /** * 自定义分区,实现长度不同的字符串,分到不同的reduce里面 * * 现在只有3个长度的字符串,所以可以把reduce的个数设置为3 * 有几个分区,就设置为几 * */ String key=arg0.toString(); if(key.length()==1){ return 1%arg2; }else if(key.length()==2){ return 2%arg2; }else if(key.length()==3){ return 3%arg2; } return 0; } } /*** * Reduce任务 * * **/ public static class PReduce extends Reducer<Text, Text, Text, Text>{ @Override protected void reduce(Text arg0, Iterable<Text> arg1, Context arg2) throws IOException, InterruptedException { String key=arg0.toString().split(",")[0]; System.out.println("key==> "+key); for(Text t:arg1){ //System.out.println("Reduce: "+arg0.toString()+" "+t.toString()); arg2.write(arg0, t); } } } public static void main(String[] args) throws Exception{ JobConf conf=new JobConf(ReadMapDB.class); //Configuration conf=new Configuration(); conf.set("mapred.job.tracker","192.168.75.130:9001"); //读取person中的数据字段 conf.setJar("tt.jar"); //注意这行代码放在最前面,进行初始化,否则会报 /**Job任务**/ Job job=new Job(conf, "testpartion"); job.setJarByClass(MyTestPartition.class); System.out.println("模式: "+conf.get("mapred.job.tracker"));; // job.setCombinerClass(PCombine.class); job.setPartitionerClass(PPartition.class); job.setNumReduceTasks(3);//设置为3 job.setMapperClass(PMapper.class); // MultipleOutputs.addNamedOutput(job, "hebei", TextOutputFormat.class, Text.class, Text.class); // MultipleOutputs.addNamedOutput(job, "henan", TextOutputFormat.class, Text.class, Text.class); job.setReducerClass(PReduce.class); job.setOutputKeyClass(Text.class); job.setOutputValueClass(Text.class); String path="hdfs://192.168.75.130:9000/root/outputdb"; FileSystem fs=FileSystem.get(conf); Path p=new Path(path); if(fs.exists(p)){ fs.delete(p, true); System.out.println("输出路径存在,已删除!"); } FileInputFormat.setInputPaths(job, "hdfs://192.168.75.130:9000/root/input"); FileOutputFormat.setOutputPath(job,p ); System.exit(job.waitForCompletion(true) ? 0 : 1); } }
如何使用eclipse调试Hadoop作业
将hadoop开发包里面的相关jar导进工程就行, 至于想调试,就看hadoop计数器返回到eclipse里的内容就可以了. 不过有一点, 如果调试的是MapReduce,速度可能不快.Hadoop,Combiner有什么用?
Combiner,Combiner号称本地的Reduce,Reduce最终的输入,是Combiner的输出。Combiner是用reducer来定义的,多数的情况下Combiner和reduce处理的是同一种逻辑,所以job.setCombinerClass()的参数可以直接使用定义的reduce。
当然也可以单独去定义一个有别于reduce的Combiner,继承Reducer,写法基本上定义reduce一样。
- fileinputformatHadoop,Combiner有什么用?相关文档
- fileinputformatmapreduce 键值对怎么定义的
- fileinputformat不同mapreduce程序可以连续运行吗?比如说多个这样的程序,用上一个的输出作为下一个的输入,求
- fileinputformathadoop 怎么设置多个输入路径
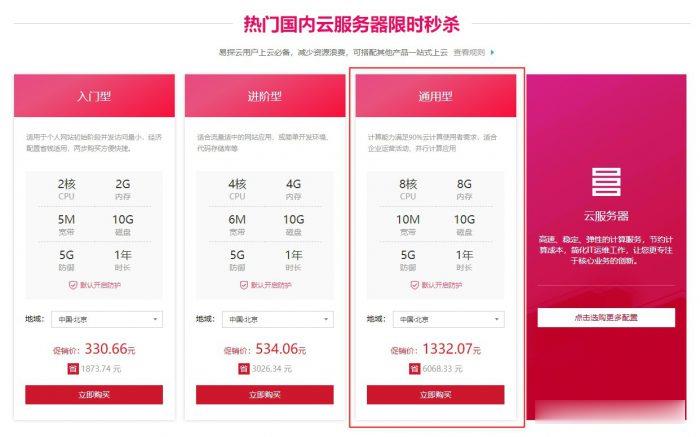
易探云(QQ音乐绿钻)北京/深圳云服务器8核8G10M带宽低至1332.07元/年起
易探云怎么样?易探云香港云服务器比较有优势,他家香港BGP+CN2口碑不错,速度也很稳定。尤其是今年他们动作很大,推出的香港云服务器有4个可用区价格低至18元起,试用过一个月的用户基本会续费,如果年付的话还可以享受8.5折或秒杀价格。今天,云服务器网(yuntue.com)小编推荐一下易探云国内云服务器优惠活动,北京和深圳这二个机房的云服务器2核2G5M带宽低至330.66元/年,还有高配云服务器...
两款半月湾 HMBcloud 春节88折日本和美国CN2 VPS主机套餐
春节期间我们很多朋友都在忙着吃好喝好,当然有时候也会偶然的上网看看。对于我们站长用户来说,基本上需要等到初八之后才会开工,现在有空就看看是否有商家的促销。这里看到来自HMBcloud半月湾服务商有提供两款春节机房方案的VPS主机88折促销活动,分别是来自洛杉矶CN2 GIA和日本CN2的方案。八八折优惠码:CNY-GIA第一、洛杉矶CN2 GIA美国原生IP地址、72小时退款保障、三网回程CN2 ...
tmhhost:暑假快乐,全高端线路,VPS直接8折,200G高防,美国gia日本软银韩国cn2香港cn2大带宽
tmhhost为2021年暑假开启了全场大促销,全部都是高端线路的VPS,速度快有保障。美国洛杉矶CN2 GIA+200G高防、洛杉矶三网CN2 GIA、洛杉矶CERA机房CN2 GIA,日本软银(100M带宽)、香港BGP直连200M带宽、香港三网CN2 GIA、韩国双向CN2。本次活动结束于8月31日。官方网站:https://www.tmhhost.com8折优惠码:TMH-SUMMER日本...
fileinputformat为你推荐
-
山东省云服务教育平台山东省云服务教育平台以前填的填的,来能改吗?自定义表情qq自定义表情单元测试规范如何做好小学数学单元测试工作电子邮件软件电子邮件软件哪个好用监控插件千里眼监控软件怎么使用啊?汤不热福利手机汤不热太卡怎么办视频比特率是什么视频码率 音频比特率多少合适?明星个人网站明星的网站地址是多少?电子词典软件手机词典下载微信电脑版2013如何下载2o13年版本微信