casesandybridge
sandybridge 时间:2021-03-27 阅读:()
PLQCDlibraryforLatticeQCDonmulti-coremachinesA.
Abdel-Rehim,aC.
Alexandrou,a,bN.
Anastopoulos,cG.
Koutsou,aI.
LiabotisdandN.
PapadopouloucaTheCyprusInstitute,CaSToRC,20KonstantinouKavaStreet,2121Aglantzia,Nicosia,CyprusbDepartmentofPhysics,UniversityofCyprus,P.
O.
Box20537,1678Nicosia,CypruscComputingSystemsLaboratory,SchoolofElectricalandComputerEngineering,NationalTechnicalUniversityofAthens,ZografouCampus,15773Zografou,Athens,GreecedGreekResearchandTechnologyNetwork,56MesogionAv.
,11527,Athens,GreeceE-mail:a.
abdel-rehim@cyi.
ac.
cy,c.
alexandrou@cyi.
ac.
cy,g.
koutsou@cyi.
ac.
cy,anastop@cslab.
ece.
ntua.
gr,iliaboti@grnet.
gr,nikela@cslab.
ece.
ntua.
grPLQCDisastand–alonesoftwarelibrarydevelopedunderPRACEforlatticeQCD.
Itpro-videsanimplementationoftheDiracoperatorforWilsontypefermionsandfewefcientlin-earsolvers.
Thelibraryisoptimizedformulti-coremachinesusingahybridparallelizationwithOpenMP+MPI.
ThemainobjectivesofthelibraryistoprovideascalableimplementationoftheDiracoperatorforefcientcomputationofthequarkpropagator.
Inthiscontribution,adescrip-tionofthePLQCDlibraryisgiventogetherwithsomebenchmarkresults.
31stInternationalSymposiumonLatticeFieldTheoryLATTICE2013July29August3,2013Mainz,GermanySpeaker.
cCopyrightownedbytheauthor(s)underthetermsoftheCreativeCommonsAttribution-NonCommercial-ShareAlikeLicence.
http://pos.
sissa.
it/arXiv:1405.
0700v1[hep-lat]4May2014PLQCDA.
Abdel-Rehim1.
IntroductionComputerhardwareforcommodityclustersaswellassupercomputershasevolvedtremen-douslyinthelastfewyears.
Nowadaysatypicalcomputenodehasbetween16and64coresandpossiblyanacceleratorsuchasaGraphicsProcessingUnit(GPU)orlatelyanIntelManyIntegratedCore(MIC)card.
Thistrendofpackingmanylow-poweredbutmassivelyparallelpro-cessingunitsisexpectedtocontinueassupercomputingtechnologypursuestheExascaleregime.
Thecurrenttechnologytrendsindicatethatbandwidthtomainmemorywillcontinuetolagbehindcomputationalpower,whichrequiresarethinkingofthedesignoflatticeQCDcodessuchthattheycanefcientlyrunonsucharchitectures.
Takingthisintoaccount,PRACE[1]allocatedresourcesforcommunitycodescalingactivitiesinmanycomputationallyintensiveareasincludinglatticeQCD.
TheworkpresentedherewasdevelopedunderPRACEfocusingonscalingcodesformulti-coremachines.
Theworkwepresentdealswithcommunitycodes,andmorespecicallyoncertaincomputationallyintensivekernelsinthesecodes,inordertoimprovetheirscalingandperformanceformulti-corearchitectures.
WehavecarriedoutoptimizationworkonthetmLQCD[2,3]codeandhavedevelopedanewhybridMPI/OpenMPlibrary(PLQCD)withoptimizedimplementationsoftheWilsonDirackernelandaselectedsetoflinearsolvers.
OurpartnersinthisprojecthavealsoperformedoptimizationworkfortheMolecularDynamicsintegratorsusedinHybridMonteCarlocodes,andalsoforLandaugaugexing.
ThiswasdonewithintheChromasoftwaresuite[4]andwillnotbediscussedhere(See[5]formoreinformation).
Manyothercommunitycodesofcourseexistbutwerenotconsideredinthiswork(See[6]foranoverview).
Inwhatfollows,wewillrstpresenttheworkcarriedoutforthecaseofPLQCD,whereweim-plementedtheWilsonDiracoperatorandassociatedlinearalgebrafunctionsusingMPI+OpenMP.
Inadditiontousingthishybridapproachforparallelism,wealsoimplementadditionaloptimiza-tionssuchasoverlappingcommunicationandcomputation,usingcompilerintrinsicsforvector-izationaswellasimplementingthenewAdvancedVectorInstructions[7](AVXforIntelorQPXforBlue/GeneQ)thatbecamerecentlyavailableinnewgenerationofprocessorssuchastheIntelSandy-Bridge.
TheworkdoneforthecaseofthetmLQCDpackagewillthenbepresented,whereweimplementedsomenewefcientlinearsolvers,inparticularthosebasedondeationsuchastheEigCGsolver[8],forwhichwewillgivesomebenchmarkresults.
2.
DiracoperatoroptimizationsAkeycomponentofthelatticeDiracoperatoristhehoppingpartgivenbyEq.
2.
1.
ψ(x)=3∑=0[U(x)(1γ)φ(x+e)+U(xe)(1+γ)φ(xe)],(2.
1)where,U(x)isthegaugelinkmatrixinthedirectionatsitex,γaretheDiracmatricesandeisaunitvectorinthedirection.
φandψaretheinputandoutputspinorsrespectively.
Equation2.
1canbere-writtenintermsoftwoauxiliaryeldsθ+(x)=(1γ)φ(x)andθ(x)=U(x)(1+γ)φ(x)asψ(x)=3∑=0[U(x)θ+(x+e)+θ(xe)].
(2.
2)2PLQCDA.
Abdel-RehimBecauseofthestructureoftheγmatrices,onlytheuppertwospincomponentsofθ±needtobecomputedbecausethelowertwospincomponentsarerelatedtotheupperones[9].
Inthefollowingwedescribesomeoftheoptimizationsperformedforthehoppingmatrix.
2.
1HybridparallelizationwithMPIandOpenMPOpenMPprovidesasimpleapproachformulti-threadingsinceitisimplementedascompilerdirectives.
Onecanincrementallyaddmulti-threadingtothecodeandalsousethesamecodewithmulti-threadingturnedonandoff.
Sincethemaincomponentinthehoppingmatrix(Diracoperator)isalarge"forloop"overlatticesites,itisnaturaltousethefor-loopparallelconstructofopenMP.
TheperformanceofthehybridcodeisthentestedagainstthepureMPIversion.
Weperformaweakscalingtestbyxingthelocalvolumepercore(orthread)andincreasethenumberofMPIprocesses.
ThetestwasdoneontheHoppermachineatNERSCwhichisaCrayXE6[10].
Eachcomputenodehas2twelve-coreAMD'MagnyCours'at2.
1-GHzsuchthateach6coressharethesamecache.
WendperformancefortheHybridversionismaximumwhenassigningatmost6threadsperMPIprocesssuchthatthese6OMPthreadssharethesameL3cache.
InFig.
1weshowtheperformanceofthepureMPIandtheMPI+openMPwith6threadsperMPIprocessforatotalnumberofcoresupto49,152cores.
FromtheseresultswerstnoticethatusingOpenMPleadstoaslightdegradationinperformanceascomparedtothepureMPIcase.
However,asweseeinthecasewithlocalvolumeof124,thehybridapproachperformsbetteraswegotoalargenumberofcores.
Similarbehaviorhasbeenalsoobservedforothercodesfromdifferentcomputationalsciences(seethecasestudiesonHopper[11]).
Figure1:WeakscalingtestforthehoppingmatrixonaCrayXE6machinewithlocallatticevolumepercore84(left)and124(right).
2.
2OverlappingcommunicationwithcomputationTypicallyinlatticecodesonerstcomputestheauxiliaryhalf-spinoreldsθ±asgiveninEquation(2.
2)andthencommunicatestheirvaluesontheboundariesbetweenneighboringpro-cessesinthe+anddirections.
Inablockingcommunicationscheme,computationhaltsuntilcommunicationoftheboundariescompletes.
Analternativeapproachistooverlapcommunica-tionswithcomputationsbydividingthelatticesitesintobulksites,forwhichnearestneighborsare3PLQCDA.
Abdel-Rehimavailablelocally,andboundarysites,forwhichthenearestneighborsarelocatedonneighboringprocesses,andthereforecanonlybeoperateduponaftercommunication.
Theorderofoperationsforcomputingtheresultψisthendoneasfollows:Computeθ+andbegincommunicatingthemtotheneighboringMPIprocessinthedirection.
ComputeθandbegincommunicatingthemtotheneighboringMPIprocessinthe+direction.
Computetheresultψ(x)onthebulksiteswhiletheneighborsarebeingcommunicated.
Waitforthecommunicationsinthedirectionstonish,thencomputethecontributions∑3=0[U(x)θ+(x+e)]totheresultontheboundarysites.
Waitforthecommunicationsinthe+directionstonish,thencomputethecontributions∑3=0[θ(xe)]ontheboundarysites.
Communicationisdoneusingnon-blockingMPIfunctionsMPI_Isend,MPI_IrecvandMPI_Wait.
Apossibledrawbackofthisapproachisthatonewillaccessψ(x)andU(x)inanunorderedfash-iondifferentfromtheorderitisstoredinmemory.
This,however,canbecircumventedpartiallybyusinghintsinthecodeforprefetching.
Wehavetestedtheeffectofprefetchingincaseofsequen-tialandrandomaccessofspinorandlinkelds.
Thetestwasdoneusingaseparatebenchmarkkernelcodewhichisolatesthelink-spinormultiplication.
AscanbeseeninFig.
3,prefetchingbecomesimportantforalargenumberofsites,i.
e.
whendata(spinorsandlinks)cannottinthecachememory,whichisatypicalsituationforlatticecalculations.
Itisalsonotedthataccessingthesitesrandomlyreducestheperformance,aswouldbeexpected.
Inthiscaseonecanimprovethesituationbydeningapointerarray,e.
g.
forthespinorsψ(i)=&ψ(x[i])wherex[i]isthesitetobeaccessedatstepiintheloopsuchasweshowinpseudo-codeinFig.
2.
Thesepointerscanbedenedapriori.
ThisimprovesthepredictiveabilityofthehardwareasisshowninFig.
3wherewecomparethedifferentprefetchingandaddressingschemes.
Sequentialaccessfor(i=0;iSandyBridgeprocessorsandlaterbyAMDintheirBull-dozerprocessor.
The16XMMregistersofSSE3arenow256-bitwideandknownasYMMregisters.
AVX-capableoatingpointunitsareabletoperformon4doubleprecisionoatingpointnumbersor8singleprecision.
Implementingtheseextensionsinthevectorizedpartsoflatticecodeshasthepotentialofprovidingagainofuptoafactor2inanidealsituation,althoughinprac-ticethisdependsonthelayoutoflatticedata.
Weprovidedanimplementationoftheseextensionsusinginlineintrinsics.
InthisimplementationasingleSU(3)matrixmultipliestwoSU(3)vectorssimultaneously.
Againofaboutafactorof1.
5isachievedforthehoppingmatrixinthetmLQCDcodeindoubleprecisionasshowninFig.
(4).
Forillustration,acodesnippetformultiplyingtwocomplexnumbersbytwocomplexnumbersusingAVXisshowninFig.
(5).
3.
EigCGsolverforTwisted-MassfermionsTwisted-MassfermionsoffertheadvantageofautomaticO(a)improvementwhentunedtomaximaltwist[12].
Withinthisdevelopmentworkwehaveaddedanincrementaldeationalgo-rithm,knownasEigCG,tothetmLQCDpackage.
Numericaltestsshowedaconsiderablespeed-upofthesolutionofthelinearsystemsonthelargestvolumessimulatedbytheEuropeanTwistedMassCollaboration(ETMC).
Forillustration,weshowinFig.
(6)thetimetosolutionwithEigCGonaTwisted-Masscongurationwith2+1+1dynamicalavorswithlatticesize483*96atβ=2.
1,andpionmass≈230MeV.
Inthiscasethetotalnumberofeigenvectorsdeatedwas300whichwasbuiltincrementallybycomputing10eigenvectorsduringthesolutionoftherst30right-handsidesusingasearchsubspaceofsize60.
Allsystemsaresolvedindoubleprecisiontorelativetoleranceof108.
5PLQCDA.
Abdel-RehimFigure4:Comparingtheperformanceofthehop-pingmatrixoftmLQCDusingSSE3andAVXindoubleprecisiononanIntelSandyBridgeprocessor.
#include/*t0:a+b*I,e+f*Iandt1:c+d*I,g+h*I*return:(ac-bd)+(ad+bc)*I,*(eg-fh)+(eh+fg)*I*/staticinline__m256dcomplex_mul_regs_256(__m256dt0,__m256dt1){__m256dt2;t2=t1;t1=_mm256_unpacklo_pd(t1,t1);t2=_mm256_unpackhi_pd(t2,t2);t1=_mm256_mul_pd(t1,t0);t2=_mm256_mul_pd(t2,t0);t2=_mm256_shuffle_pd(t2,t2,5);t1=_mm256_addsub_pd(t1,t2);returnt1;}Figure5:MultiplyingtwocomplexnumbersbytwocomplexnumberoftypedoubleusingAVXin-structions.
Figure6:Solutiontimeperprocessfortherst35right-handsidesusingIncrementalEigCGascomparedtoCGonaTwisted-Masscongurationwithlatticesize483*96atβ=2.
1,andpionmass≈230MeV.
4.
ConclusionsandSummaryWehavecarriedoutdevelopmenteffortforafewselectedkernelsusedinlatticeQCD.
TherstoftheseeffortsincludedthedevelopmentofahybridMPI/OpenMPlibrarywhichincludesparallelizedkernelsfortheWilsonDiracoperatorandfewassociatedsolvers.
Anumberofparal-lelizationstrategieshavebeeninvestigated,suchasforoverlappingcommunicationwithcomputa-tions.
ThecodehasbeenshowntoscalefairlywellontheCrayXE6.
Intermsofsingleprocessperformance,wecarriedoutinitialvectorizationeffortsforAVXwhereweseeanimprovementof1.
5comparedtotheideal2.
Inadditionwehaveinvestigatedseveraldata-orderingandassociatedprefetchingstrategies.
ForthecaseoftmLQCD,themainsoftwarecodeoftheETMCcollaboration,wehaveimple-6PLQCDA.
Abdel-Rehimmentedanefcientlinearsolverwhichincrementallydeatedthetwisted-massDiracoperatortogiveaspeed-upofabout3timeswhenenoughright-hand-sidesarerequired.
Thisisalreadyinuseinproductionprojects,suchasinRefs.
[14]and[13].
Allcodesarepubliclyavailable.
PLQCDisavailablethroughtheHPCFORGEwebsiteattheSwissNationalSupercomputingCentre(CSCS)wheremoreinformationisavailablewithinthecodedocumentation.
OurEigCGimplementationintmLQCDisavailableviagit-hub.
AcknowledgementsThistalkwasapartofacodingsessionsponsoredpartiallybythePRACE-2IPproject,aspartofthe"CommunityCodesDevelopment"WorkPackage8.
PRACE-2IPisa7thFrameworkEUfundedproject(http://www.
prace-ri.
eu/,grantagreementnumber:RI-283493).
Wewouldliketothanktheorganizersofthe2013Latticemeetingfortheirstrongsupporttomakethecodingsessionasuccessandprovideallorganizationsupport.
WewouldliketothankC.
Urbach,A.
Deuzmann,B.
Kostrzewa,HubertSimma,S.
Krieg,andL.
Scorzatoforverystimulatingdiscussionsduringthedevelopmentofthisproject.
WeacknowledgethecomputingresourcesfromTier-0machinesofPRACEincludingJUQUEENandCuriemachinesaswellastheTodimachineatCSCS.
WealsoacknowledgethecomputingsupportfromNERSCandtheHoppermachine.
References[1]http://www.
prace-ri.
eu/.
[2]K.
JansenandC.
Urbach,Comput.
Phys.
Commun.
180,2717(2009),[arXiv:0905.
3331].
[3]ETMCollaboration,https://github.
com/etmc/tmLQCD.
[4]http://usqcd.
jlab.
org/usqcd-docs/chroma/.
[5]SeethepublicdeliverableD8.
3onthePRACEwebsiteunderPRACE-2IP.
[6]A.
Deuzeman,PoS(LATTICE2013).
[7]SeetheIntelDevelopermanual.
[8]A.
StathopoulosandK.
Orginos,Computinganddeatingeigenvalueswhilesolvingmultipleright-handsidelinearsystemswithanapplicationtoquantumchromodynamics,SIAMJ.
Sci.
Comput.
2010;32(1):439–462,[arXiv:0707.
0131].
[9]SeeforexamplethedocumentationoftheDDHMCcodebyM.
L¨uscher.
[10]TheHopperCrayXE6machineatNERSC.
[11]SeedocumentationforcombiningMPIandopenMPontheNERSCwebsite.
[12]R.
Frezzottietal.
[AlphaCollaboration],LatticeQCDwithachirallytwistedmassterm,JHEP0108,058(2001)[hep-lat/0101001].
[13]C.
Alexandrou,M.
Constantinou,S.
Dinter,V.
Drach,K.
Hadjiyiannakou,K.
Jansen,G.
KoutsouandA.
Vaquero,arXiv:1309.
7768[hep-lat].
[14]A.
Abdel-Rehim,C.
Alexandrou,M.
Constantinou,V.
Drach,K.
Hadjiyiannakou,K.
Jansen,G.
KoutsouandA.
Vaquero,arXiv:1310.
6339[hep-lat].
7
Abdel-Rehim,aC.
Alexandrou,a,bN.
Anastopoulos,cG.
Koutsou,aI.
LiabotisdandN.
PapadopouloucaTheCyprusInstitute,CaSToRC,20KonstantinouKavaStreet,2121Aglantzia,Nicosia,CyprusbDepartmentofPhysics,UniversityofCyprus,P.
O.
Box20537,1678Nicosia,CypruscComputingSystemsLaboratory,SchoolofElectricalandComputerEngineering,NationalTechnicalUniversityofAthens,ZografouCampus,15773Zografou,Athens,GreecedGreekResearchandTechnologyNetwork,56MesogionAv.
,11527,Athens,GreeceE-mail:a.
abdel-rehim@cyi.
ac.
cy,c.
alexandrou@cyi.
ac.
cy,g.
koutsou@cyi.
ac.
cy,anastop@cslab.
ece.
ntua.
gr,iliaboti@grnet.
gr,nikela@cslab.
ece.
ntua.
grPLQCDisastand–alonesoftwarelibrarydevelopedunderPRACEforlatticeQCD.
Itpro-videsanimplementationoftheDiracoperatorforWilsontypefermionsandfewefcientlin-earsolvers.
Thelibraryisoptimizedformulti-coremachinesusingahybridparallelizationwithOpenMP+MPI.
ThemainobjectivesofthelibraryistoprovideascalableimplementationoftheDiracoperatorforefcientcomputationofthequarkpropagator.
Inthiscontribution,adescrip-tionofthePLQCDlibraryisgiventogetherwithsomebenchmarkresults.
31stInternationalSymposiumonLatticeFieldTheoryLATTICE2013July29August3,2013Mainz,GermanySpeaker.
cCopyrightownedbytheauthor(s)underthetermsoftheCreativeCommonsAttribution-NonCommercial-ShareAlikeLicence.
http://pos.
sissa.
it/arXiv:1405.
0700v1[hep-lat]4May2014PLQCDA.
Abdel-Rehim1.
IntroductionComputerhardwareforcommodityclustersaswellassupercomputershasevolvedtremen-douslyinthelastfewyears.
Nowadaysatypicalcomputenodehasbetween16and64coresandpossiblyanacceleratorsuchasaGraphicsProcessingUnit(GPU)orlatelyanIntelManyIntegratedCore(MIC)card.
Thistrendofpackingmanylow-poweredbutmassivelyparallelpro-cessingunitsisexpectedtocontinueassupercomputingtechnologypursuestheExascaleregime.
Thecurrenttechnologytrendsindicatethatbandwidthtomainmemorywillcontinuetolagbehindcomputationalpower,whichrequiresarethinkingofthedesignoflatticeQCDcodessuchthattheycanefcientlyrunonsucharchitectures.
Takingthisintoaccount,PRACE[1]allocatedresourcesforcommunitycodescalingactivitiesinmanycomputationallyintensiveareasincludinglatticeQCD.
TheworkpresentedherewasdevelopedunderPRACEfocusingonscalingcodesformulti-coremachines.
Theworkwepresentdealswithcommunitycodes,andmorespecicallyoncertaincomputationallyintensivekernelsinthesecodes,inordertoimprovetheirscalingandperformanceformulti-corearchitectures.
WehavecarriedoutoptimizationworkonthetmLQCD[2,3]codeandhavedevelopedanewhybridMPI/OpenMPlibrary(PLQCD)withoptimizedimplementationsoftheWilsonDirackernelandaselectedsetoflinearsolvers.
OurpartnersinthisprojecthavealsoperformedoptimizationworkfortheMolecularDynamicsintegratorsusedinHybridMonteCarlocodes,andalsoforLandaugaugexing.
ThiswasdonewithintheChromasoftwaresuite[4]andwillnotbediscussedhere(See[5]formoreinformation).
Manyothercommunitycodesofcourseexistbutwerenotconsideredinthiswork(See[6]foranoverview).
Inwhatfollows,wewillrstpresenttheworkcarriedoutforthecaseofPLQCD,whereweim-plementedtheWilsonDiracoperatorandassociatedlinearalgebrafunctionsusingMPI+OpenMP.
Inadditiontousingthishybridapproachforparallelism,wealsoimplementadditionaloptimiza-tionssuchasoverlappingcommunicationandcomputation,usingcompilerintrinsicsforvector-izationaswellasimplementingthenewAdvancedVectorInstructions[7](AVXforIntelorQPXforBlue/GeneQ)thatbecamerecentlyavailableinnewgenerationofprocessorssuchastheIntelSandy-Bridge.
TheworkdoneforthecaseofthetmLQCDpackagewillthenbepresented,whereweimplementedsomenewefcientlinearsolvers,inparticularthosebasedondeationsuchastheEigCGsolver[8],forwhichwewillgivesomebenchmarkresults.
2.
DiracoperatoroptimizationsAkeycomponentofthelatticeDiracoperatoristhehoppingpartgivenbyEq.
2.
1.
ψ(x)=3∑=0[U(x)(1γ)φ(x+e)+U(xe)(1+γ)φ(xe)],(2.
1)where,U(x)isthegaugelinkmatrixinthedirectionatsitex,γaretheDiracmatricesandeisaunitvectorinthedirection.
φandψaretheinputandoutputspinorsrespectively.
Equation2.
1canbere-writtenintermsoftwoauxiliaryeldsθ+(x)=(1γ)φ(x)andθ(x)=U(x)(1+γ)φ(x)asψ(x)=3∑=0[U(x)θ+(x+e)+θ(xe)].
(2.
2)2PLQCDA.
Abdel-RehimBecauseofthestructureoftheγmatrices,onlytheuppertwospincomponentsofθ±needtobecomputedbecausethelowertwospincomponentsarerelatedtotheupperones[9].
Inthefollowingwedescribesomeoftheoptimizationsperformedforthehoppingmatrix.
2.
1HybridparallelizationwithMPIandOpenMPOpenMPprovidesasimpleapproachformulti-threadingsinceitisimplementedascompilerdirectives.
Onecanincrementallyaddmulti-threadingtothecodeandalsousethesamecodewithmulti-threadingturnedonandoff.
Sincethemaincomponentinthehoppingmatrix(Diracoperator)isalarge"forloop"overlatticesites,itisnaturaltousethefor-loopparallelconstructofopenMP.
TheperformanceofthehybridcodeisthentestedagainstthepureMPIversion.
Weperformaweakscalingtestbyxingthelocalvolumepercore(orthread)andincreasethenumberofMPIprocesses.
ThetestwasdoneontheHoppermachineatNERSCwhichisaCrayXE6[10].
Eachcomputenodehas2twelve-coreAMD'MagnyCours'at2.
1-GHzsuchthateach6coressharethesamecache.
WendperformancefortheHybridversionismaximumwhenassigningatmost6threadsperMPIprocesssuchthatthese6OMPthreadssharethesameL3cache.
InFig.
1weshowtheperformanceofthepureMPIandtheMPI+openMPwith6threadsperMPIprocessforatotalnumberofcoresupto49,152cores.
FromtheseresultswerstnoticethatusingOpenMPleadstoaslightdegradationinperformanceascomparedtothepureMPIcase.
However,asweseeinthecasewithlocalvolumeof124,thehybridapproachperformsbetteraswegotoalargenumberofcores.
Similarbehaviorhasbeenalsoobservedforothercodesfromdifferentcomputationalsciences(seethecasestudiesonHopper[11]).
Figure1:WeakscalingtestforthehoppingmatrixonaCrayXE6machinewithlocallatticevolumepercore84(left)and124(right).
2.
2OverlappingcommunicationwithcomputationTypicallyinlatticecodesonerstcomputestheauxiliaryhalf-spinoreldsθ±asgiveninEquation(2.
2)andthencommunicatestheirvaluesontheboundariesbetweenneighboringpro-cessesinthe+anddirections.
Inablockingcommunicationscheme,computationhaltsuntilcommunicationoftheboundariescompletes.
Analternativeapproachistooverlapcommunica-tionswithcomputationsbydividingthelatticesitesintobulksites,forwhichnearestneighborsare3PLQCDA.
Abdel-Rehimavailablelocally,andboundarysites,forwhichthenearestneighborsarelocatedonneighboringprocesses,andthereforecanonlybeoperateduponaftercommunication.
Theorderofoperationsforcomputingtheresultψisthendoneasfollows:Computeθ+andbegincommunicatingthemtotheneighboringMPIprocessinthedirection.
ComputeθandbegincommunicatingthemtotheneighboringMPIprocessinthe+direction.
Computetheresultψ(x)onthebulksiteswhiletheneighborsarebeingcommunicated.
Waitforthecommunicationsinthedirectionstonish,thencomputethecontributions∑3=0[U(x)θ+(x+e)]totheresultontheboundarysites.
Waitforthecommunicationsinthe+directionstonish,thencomputethecontributions∑3=0[θ(xe)]ontheboundarysites.
Communicationisdoneusingnon-blockingMPIfunctionsMPI_Isend,MPI_IrecvandMPI_Wait.
Apossibledrawbackofthisapproachisthatonewillaccessψ(x)andU(x)inanunorderedfash-iondifferentfromtheorderitisstoredinmemory.
This,however,canbecircumventedpartiallybyusinghintsinthecodeforprefetching.
Wehavetestedtheeffectofprefetchingincaseofsequen-tialandrandomaccessofspinorandlinkelds.
Thetestwasdoneusingaseparatebenchmarkkernelcodewhichisolatesthelink-spinormultiplication.
AscanbeseeninFig.
3,prefetchingbecomesimportantforalargenumberofsites,i.
e.
whendata(spinorsandlinks)cannottinthecachememory,whichisatypicalsituationforlatticecalculations.
Itisalsonotedthataccessingthesitesrandomlyreducestheperformance,aswouldbeexpected.
Inthiscaseonecanimprovethesituationbydeningapointerarray,e.
g.
forthespinorsψ(i)=&ψ(x[i])wherex[i]isthesitetobeaccessedatstepiintheloopsuchasweshowinpseudo-codeinFig.
2.
Thesepointerscanbedenedapriori.
ThisimprovesthepredictiveabilityofthehardwareasisshowninFig.
3wherewecomparethedifferentprefetchingandaddressingschemes.
Sequentialaccessfor(i=0;iSandyBridgeprocessorsandlaterbyAMDintheirBull-dozerprocessor.
The16XMMregistersofSSE3arenow256-bitwideandknownasYMMregisters.
AVX-capableoatingpointunitsareabletoperformon4doubleprecisionoatingpointnumbersor8singleprecision.
Implementingtheseextensionsinthevectorizedpartsoflatticecodeshasthepotentialofprovidingagainofuptoafactor2inanidealsituation,althoughinprac-ticethisdependsonthelayoutoflatticedata.
Weprovidedanimplementationoftheseextensionsusinginlineintrinsics.
InthisimplementationasingleSU(3)matrixmultipliestwoSU(3)vectorssimultaneously.
Againofaboutafactorof1.
5isachievedforthehoppingmatrixinthetmLQCDcodeindoubleprecisionasshowninFig.
(4).
Forillustration,acodesnippetformultiplyingtwocomplexnumbersbytwocomplexnumbersusingAVXisshowninFig.
(5).
3.
EigCGsolverforTwisted-MassfermionsTwisted-MassfermionsoffertheadvantageofautomaticO(a)improvementwhentunedtomaximaltwist[12].
Withinthisdevelopmentworkwehaveaddedanincrementaldeationalgo-rithm,knownasEigCG,tothetmLQCDpackage.
Numericaltestsshowedaconsiderablespeed-upofthesolutionofthelinearsystemsonthelargestvolumessimulatedbytheEuropeanTwistedMassCollaboration(ETMC).
Forillustration,weshowinFig.
(6)thetimetosolutionwithEigCGonaTwisted-Masscongurationwith2+1+1dynamicalavorswithlatticesize483*96atβ=2.
1,andpionmass≈230MeV.
Inthiscasethetotalnumberofeigenvectorsdeatedwas300whichwasbuiltincrementallybycomputing10eigenvectorsduringthesolutionoftherst30right-handsidesusingasearchsubspaceofsize60.
Allsystemsaresolvedindoubleprecisiontorelativetoleranceof108.
5PLQCDA.
Abdel-RehimFigure4:Comparingtheperformanceofthehop-pingmatrixoftmLQCDusingSSE3andAVXindoubleprecisiononanIntelSandyBridgeprocessor.
#include/*t0:a+b*I,e+f*Iandt1:c+d*I,g+h*I*return:(ac-bd)+(ad+bc)*I,*(eg-fh)+(eh+fg)*I*/staticinline__m256dcomplex_mul_regs_256(__m256dt0,__m256dt1){__m256dt2;t2=t1;t1=_mm256_unpacklo_pd(t1,t1);t2=_mm256_unpackhi_pd(t2,t2);t1=_mm256_mul_pd(t1,t0);t2=_mm256_mul_pd(t2,t0);t2=_mm256_shuffle_pd(t2,t2,5);t1=_mm256_addsub_pd(t1,t2);returnt1;}Figure5:MultiplyingtwocomplexnumbersbytwocomplexnumberoftypedoubleusingAVXin-structions.
Figure6:Solutiontimeperprocessfortherst35right-handsidesusingIncrementalEigCGascomparedtoCGonaTwisted-Masscongurationwithlatticesize483*96atβ=2.
1,andpionmass≈230MeV.
4.
ConclusionsandSummaryWehavecarriedoutdevelopmenteffortforafewselectedkernelsusedinlatticeQCD.
TherstoftheseeffortsincludedthedevelopmentofahybridMPI/OpenMPlibrarywhichincludesparallelizedkernelsfortheWilsonDiracoperatorandfewassociatedsolvers.
Anumberofparal-lelizationstrategieshavebeeninvestigated,suchasforoverlappingcommunicationwithcomputa-tions.
ThecodehasbeenshowntoscalefairlywellontheCrayXE6.
Intermsofsingleprocessperformance,wecarriedoutinitialvectorizationeffortsforAVXwhereweseeanimprovementof1.
5comparedtotheideal2.
Inadditionwehaveinvestigatedseveraldata-orderingandassociatedprefetchingstrategies.
ForthecaseoftmLQCD,themainsoftwarecodeoftheETMCcollaboration,wehaveimple-6PLQCDA.
Abdel-Rehimmentedanefcientlinearsolverwhichincrementallydeatedthetwisted-massDiracoperatortogiveaspeed-upofabout3timeswhenenoughright-hand-sidesarerequired.
Thisisalreadyinuseinproductionprojects,suchasinRefs.
[14]and[13].
Allcodesarepubliclyavailable.
PLQCDisavailablethroughtheHPCFORGEwebsiteattheSwissNationalSupercomputingCentre(CSCS)wheremoreinformationisavailablewithinthecodedocumentation.
OurEigCGimplementationintmLQCDisavailableviagit-hub.
AcknowledgementsThistalkwasapartofacodingsessionsponsoredpartiallybythePRACE-2IPproject,aspartofthe"CommunityCodesDevelopment"WorkPackage8.
PRACE-2IPisa7thFrameworkEUfundedproject(http://www.
prace-ri.
eu/,grantagreementnumber:RI-283493).
Wewouldliketothanktheorganizersofthe2013Latticemeetingfortheirstrongsupporttomakethecodingsessionasuccessandprovideallorganizationsupport.
WewouldliketothankC.
Urbach,A.
Deuzmann,B.
Kostrzewa,HubertSimma,S.
Krieg,andL.
Scorzatoforverystimulatingdiscussionsduringthedevelopmentofthisproject.
WeacknowledgethecomputingresourcesfromTier-0machinesofPRACEincludingJUQUEENandCuriemachinesaswellastheTodimachineatCSCS.
WealsoacknowledgethecomputingsupportfromNERSCandtheHoppermachine.
References[1]http://www.
prace-ri.
eu/.
[2]K.
JansenandC.
Urbach,Comput.
Phys.
Commun.
180,2717(2009),[arXiv:0905.
3331].
[3]ETMCollaboration,https://github.
com/etmc/tmLQCD.
[4]http://usqcd.
jlab.
org/usqcd-docs/chroma/.
[5]SeethepublicdeliverableD8.
3onthePRACEwebsiteunderPRACE-2IP.
[6]A.
Deuzeman,PoS(LATTICE2013).
[7]SeetheIntelDevelopermanual.
[8]A.
StathopoulosandK.
Orginos,Computinganddeatingeigenvalueswhilesolvingmultipleright-handsidelinearsystemswithanapplicationtoquantumchromodynamics,SIAMJ.
Sci.
Comput.
2010;32(1):439–462,[arXiv:0707.
0131].
[9]SeeforexamplethedocumentationoftheDDHMCcodebyM.
L¨uscher.
[10]TheHopperCrayXE6machineatNERSC.
[11]SeedocumentationforcombiningMPIandopenMPontheNERSCwebsite.
[12]R.
Frezzottietal.
[AlphaCollaboration],LatticeQCDwithachirallytwistedmassterm,JHEP0108,058(2001)[hep-lat/0101001].
[13]C.
Alexandrou,M.
Constantinou,S.
Dinter,V.
Drach,K.
Hadjiyiannakou,K.
Jansen,G.
KoutsouandA.
Vaquero,arXiv:1309.
7768[hep-lat].
[14]A.
Abdel-Rehim,C.
Alexandrou,M.
Constantinou,V.
Drach,K.
Hadjiyiannakou,K.
Jansen,G.
KoutsouandA.
Vaquero,arXiv:1310.
6339[hep-lat].
7
- casesandybridge相关文档
- E5sandybridge
- PenguinComputingClustersandybridge
- cumulativesandybridge
- 5.sandybridge
- 希捷sandybridge
- layerssandybridge
CloudCone2核KVM美国洛杉矶MC机房机房2.89美元/月,美国洛杉矶MC机房KVM虚拟架构2核1.5G内存1Gbps带宽,国外便宜美国VPS七月特价优惠
近日CloudCone发布了七月的特价便宜优惠VPS云服务器产品,KVM虚拟架构,性价比最高的为2核心1.5G内存1Gbps带宽5TB月流量,2.89美元/月,稳定性还是非常不错的,有需要国外便宜VPS云服务器的朋友可以关注一下。CloudCone怎么样?CloudCone服务器好不好?CloudCone值不值得购买?CloudCone是一家成立于2017年的美国服务器提供商,国外实力大厂,自己开...
DogYun香港BGP月付14.4元主机简单测试
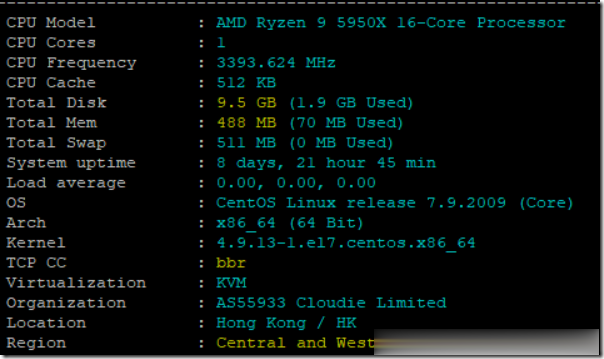
前些天赵容分享过DogYun(狗云)香港BGP线路AMD 5950X经典低价云服务器的信息(点击查看),刚好账户还有点余额够开个最低配,所以手贱尝试下,这些贴上简单测试信息,方便大家参考。官方网站:www.dogyun.com主机配置我搞的是最低款优惠后14.4元/月的,配置单核,512MB内存,10GB硬盘,300GB/50Mbps月流量。基本信息DogYun的VPS主机管理集成在会员中心,包括...
SugarHosts糖果主机圣诞节促销 美国/香港虚拟主机低至6折
SugarHosts 糖果主机商我们算是比较熟悉的,早年学会建站的时候开始就用的糖果虚拟主机,目前他们家还算是为数不多提供虚拟主机的商家,有提供香港、美国、德国等虚拟主机机房。香港机房CN2速度比较快,美国机房有提供优化线路和普通线路适合外贸业务。德国欧洲机房适合欧洲业务的虚拟主机。糖果主机商一般是不会发布黑五活动的,他们在圣圣诞节促销活动是有的,我们看到糖果主机商发布的圣诞节促销虚拟主机低至6折...
sandybridge为你推荐
-
公司网络被攻击网络遭受攻击分为哪几类中老铁路一带一路的火车是什么火车access数据库ACCESS数据库有什么用www.hao360.cn主页设置为http://hao.360.cn/,但打开360浏览器先显示www.yes125.com后转换为www.2345.com,搜索注册表和李子柒年入1.6亿魔兽rpg箱庭世界1.6怎么进入魔门比肩工场比肩是什么意思,行比肩大运的主要意象www.e12.com.cn有什么好的高中学习网?javbibitreebibi是什么牌子的梦遗姐昨晚和姐姐和她朋友一起吃晚饭,我们都喝了酒,我迷糊着回到家的,早上我回想起我好像发生关系射过,会不会是我姐姐,如果是这样我怎么办hao.rising.cn我一打开网页就是瑞星安全网站导航,怎么修改?